Pick the tool that shows you the answers behind the number, not the one with the prettiest score. Peec suits teams starting out, Profound suits enterprise programmes, and OtterlyAI suits agencies on a budget. Whatever you buy, fix your counting rule first. A Share of Answer figure nobody can reproduce will not survive a leadership meeting.
That shortlist holds for a B2B SaaS team tracking ChatGPT, Perplexity and Google AI Overviews with a first set of 30 to 50 prompts. Across several regions, or if you need more engines than the other plans cover, Profound's enterprise tier becomes the comparison.
No tool removes answer variance, so one run of 30 prompts at a 30% mention rate can swing by roughly 16 points either way, and the number needs repeat runs before it goes in front of anyone.
If you would rather have a team build the prompt set and scorecard with you, see our Generative Engine Optimization service.
📋 Get Listed / Advertise
We update this guide monthly. Want your tool featured? Contact: [email protected].
Share Of Answer Tools At A Glance
Peec is best for starting a baseline, Profound for enterprise category reporting, OtterlyAI for agencies and multi-brand workspaces, Promptmonitor for finding lost prompts and sources, and Akii for cross-engine mention tracking. All five are judged against the measurement policy set out in the evaluation section lower on this page, called What To Look For In An AI Visibility Tool.
| Tool | Best for | Engines or models covered | Plan limits | Pricing |
|---|---|---|---|---|
| Peec | Starting a Share of Answer baseline | 3 models on Starter, Pro and Advanced, up to 13 on Enterprise | 50 prompts on Starter, 150 on Pro, 350 on Advanced | No list price on the pricing page, Enterprise by quote |
| Profound | Enterprise-scale category reporting | Up to 9 answer engines on Enterprise | Custom Enterprise packages, 400 AI Marketer credits a month per client workspace on Agency Growth | Custom, demo required |
| OtterlyAI | Agencies and multi-brand workspaces | ChatGPT, Google AI Overviews, Perplexity and Microsoft Copilot on all plans, three more as add-ons | 15 prompts on Lite, 100 on Standard, 400 on Premium | $29, $189 and $489 a month, Enterprise custom |
| Promptmonitor | Finding lost prompts and sources | Multiple LLMs including ChatGPT and Perplexity | Ask the vendor | Pricing on request |
| Akii | Cross-engine mention tracking | Google AI, ChatGPT and Perplexity among others | Ask the vendor | Pricing on request |
1. Peec: Best For Starting A Share Of Answer Baseline
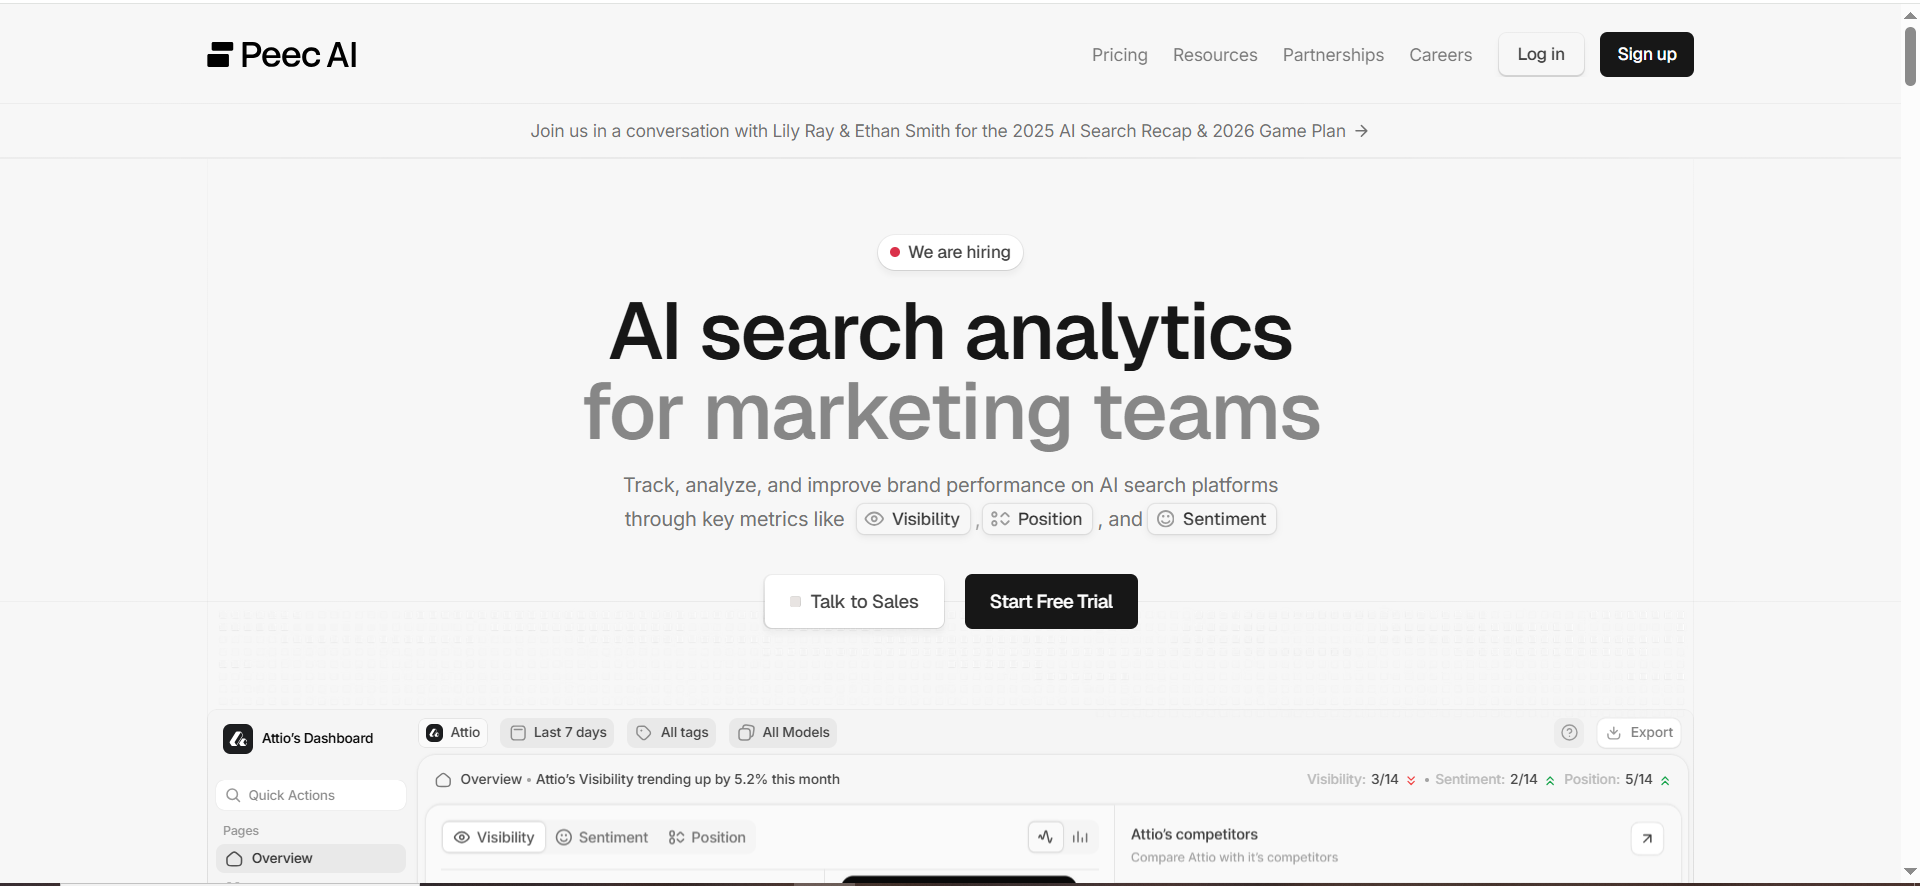
Peec is an AI search analytics platform where you define the prompts that matter and monitor whether your brand is present in the answers, and how that compares with competitors. Pick it when you are building a Share of Answer baseline from nothing, because the Starter plan gives you 50 prompts across 3 models with daily tracking and up to 4,500 AI answers a month, according to Peec's pricing page.
Most teams do not need forty dashboards to begin. They need a consistent prompt set, a visibility signal they can trend, and a simple way to show whether they are winning or losing share. Peec fits growth-stage B2B SaaS teams building a GEO or AEO programme from scratch, SEO teams that want an AI layer on top of their keyword strategy, and marketing orgs that need exec-readable outputs fast.
Pricing: Peec shows plan limits for every tier and a list price for none of the first three.
| Plan | Price | Prompts | Models | Projects | Answers per month |
|---|---|---|---|---|---|
| Starter | Not listed | 50 | 3 | 1 | 4,500 |
| Pro | Not listed | 150 | 3 | 2 | 13,500 |
| Advanced | Not listed | 350 | 3 | 5 | 31,500 |
| Enterprise | Custom | Not listed | Up to 13 | Unlimited | Not listed |
Peec's pricing page shows monthly plans, with Enterprise billed annually by quote. Daily tracking runs on Starter, Pro and Advanced. Advanced adds multi-country tracking and a Looker Studio integration, and API access and SSO are Enterprise only. The page gives no free tier detail, so ask Peec directly before you plan around a trial.
Strengths:
- Daily tracking and unlimited users from the entry plan.
- Plan limits stated plainly, so you can work out answers per month before you buy.
- Looker Studio integration on Advanced, which makes the exec view easy to build.
Trade-offs:
- No list price for Starter, Pro or Advanced, so you cannot budget without talking to sales.
- Three models on every plan below Enterprise.
- API access and SSO only on Enterprise.
Key capabilities:
- Prompt tracking with competitor comparison.
- Group prompts into categories and competitor sets.
- Trend visibility over time and export results for dashboards.
Good fit:
- A growth-stage B2B SaaS team starting a GEO or AEO programme.
- An SEO team adding an AI layer to existing keyword work.
Not a fit:
- Teams that need deep governance workflows, multi-region compliance or custom data pipelines on day one.
- Teams that want heavily customised internal model scoring, which you can still run but at the cost of extra ops.
How to use it in your first month:
- Start with 30 to 50 prompts across your highest-value product categories and competitor comparisons.
- Tag prompts by intent, such as alternatives, best X, pricing and integration.
- Track weekly for four weeks to establish variance, then decide whether you need daily monitoring.
- Export a simple exec view with overall Share of Answer, share by category and the top prompts you are losing.
The biggest limitation is measurement nuance. If your exec team expects one perfect KPI, you still need your own definitions for weighting, prominence and prompt volume, and that is true of every entry-level tool in this category.
2. Profound: Best For Enterprise-Scale Category Reporting
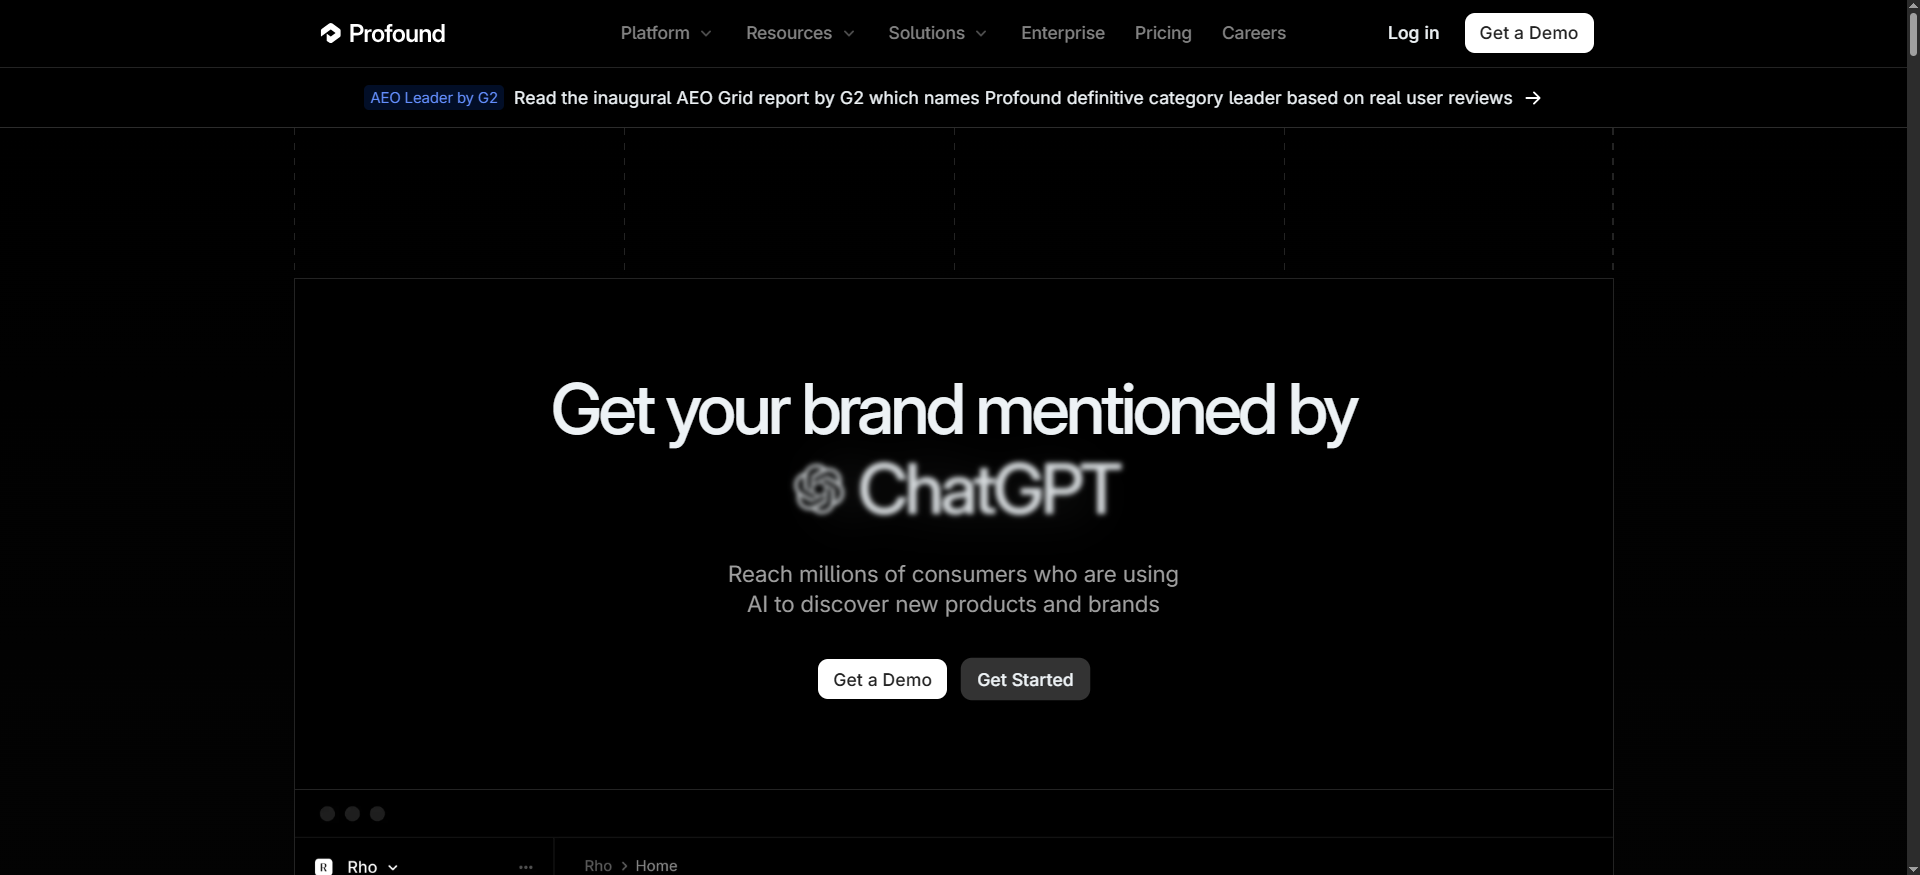
Profound optimises brand visibility in AI search by tracking performance across AI-driven discovery, and it is the one to evaluate when enterprise scale is the question. On Enterprise it covers up to 9 answer engines and offers CSV and JSON export, an API and SSO/SAML, all listed on Profound's pricing page.
If Peec is the start-measuring-now option, Profound is what teams look at when they ask three things. Can we measure this at enterprise scale? Can we connect it to category strategy and market perception? Can we run AI visibility as a durable programme rather than a one-off experiment? It suits enterprise or late-stage growth teams supporting several product lines or regions, and anyone expected to deliver board-ready reporting on how the AI channel is doing.
Pricing: Profound lists no per-plan prices and directs buyers to a demo.
| Plan | Price | What it includes |
|---|---|---|
| Enterprise | Custom, demo required | Up to 9 answer engines, tailored prompt tracking, CSV and JSON export, API, SSO/SAML, ChatGPT Shopping, dedicated support |
| Agency Growth | Not published | Self-serve, 400 AI Marketer credits a month per client workspace |
The details above come from Profound's pricing page. Enterprise needs a demo before you see a number. Agency Growth is the self-serve option, and the page publishes no price for it either. There is no public free tier, so the demo is your trial.
Strengths:
- Up to 9 answer engines on Enterprise, per the vendor page.
- CSV and JSON export plus an API, which suits teams feeding a BI tool.
- Market-level reporting, so you can show visibility by theme or category rather than by prompt.
Trade-offs:
- No published prices, so budgeting starts with a sales call.
- Heavy for a small prompt list or a single brand.
- The main risk is tool adoption. If you buy an enterprise platform and skip prompt taxonomy, governance and reporting habits, the data turns into interesting charts instead of decisions.
Key capabilities:
- Category and group reporting, not just prompt lists.
- Competitive benchmarking views and trend reporting.
- Export options for internal BI.
Good fit:
- Enterprise or late-stage growth teams.
- Teams supporting multiple product lines or regions.
- Agencies that want a self-serve workspace per client.
Not a fit:
- A small number of prompts.
- A lightweight visibility score.
- A scrappy workflow for a single brand.
How to use it well comes down to four moves. Define the categories you want to own in AI answers. Build a prompt universe that maps to them. Set competitor sets per category, not one global set. Then report at three levels, overall, category and prompt cluster.
The limitation that matters most is that a platform this size only pays back if someone owns the reporting habit every week.
3. OtterlyAI: Best For Agencies And Multi-Brand Workspaces
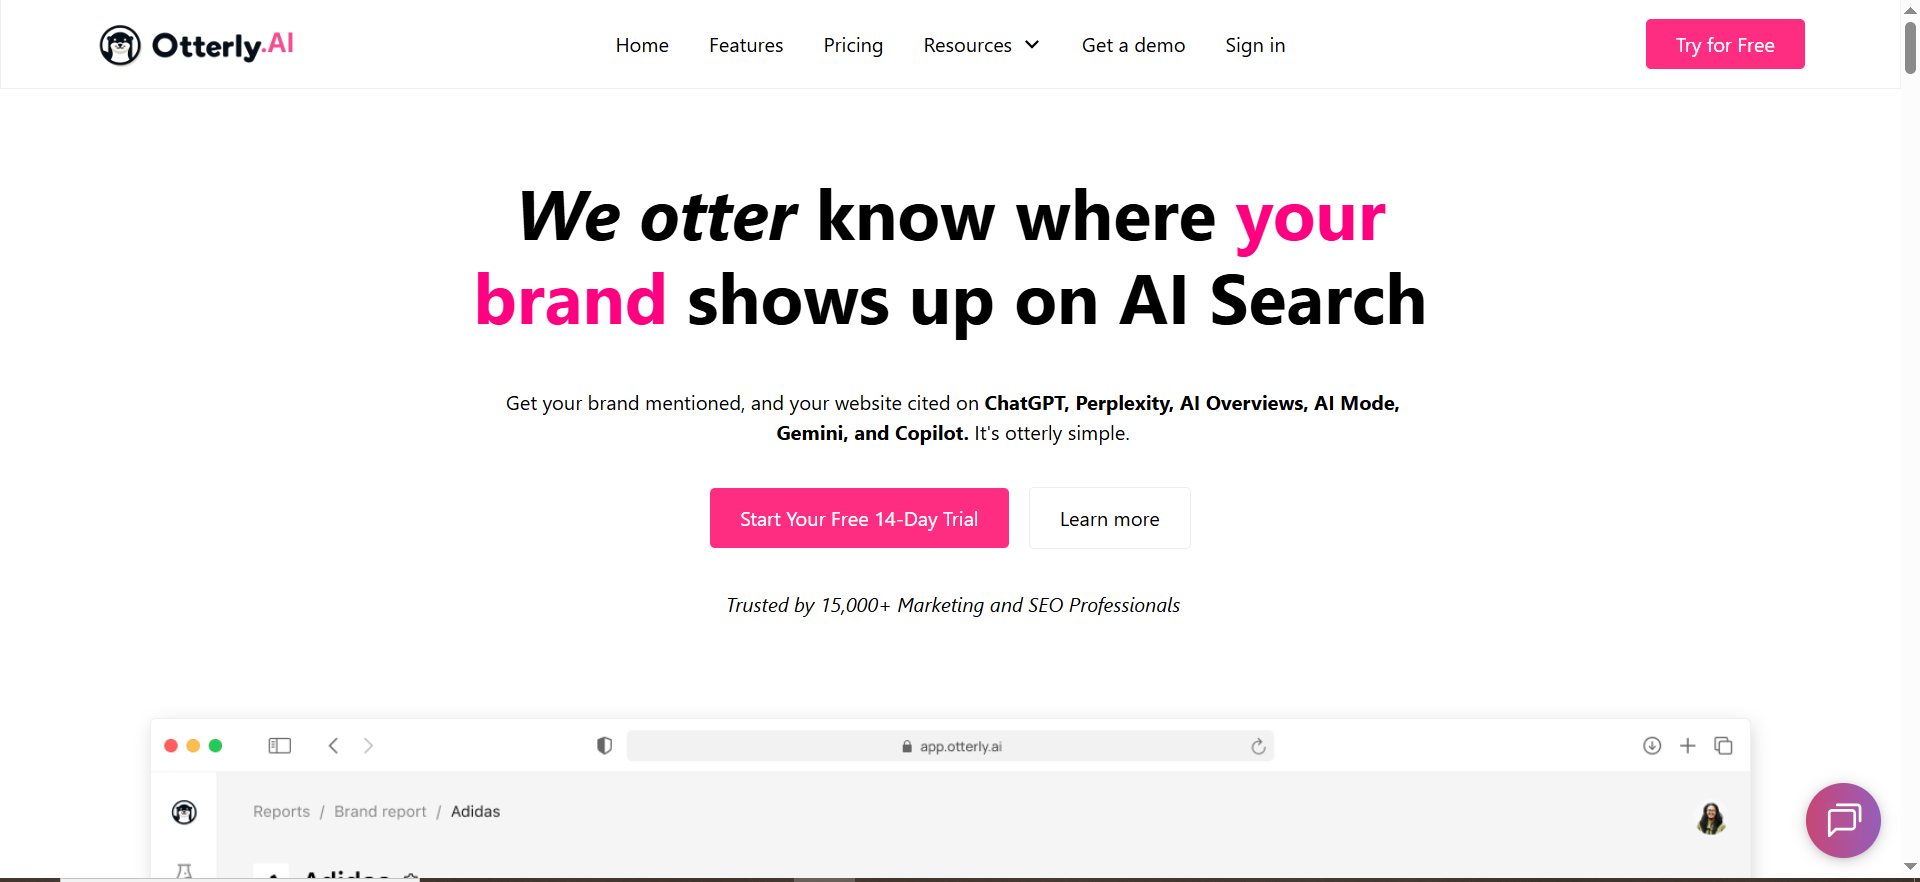
OtterlyAI is an AI visibility tracker that runs prompts against AI search engines and analyses the responses for brand mentions. It is the only one of the five that publishes its prices on the vendor page, and its Lite, Standard and Premium plans cost $29, $189 and $489 a month for 15, 100 and 400 prompts, according to OtterlyAI's pricing page.
Workspace organisation is what makes it an agency tool. Teams choose it when they want a clear AI visibility toolkit, client-style organisation, and monitoring that works for both internal teams and agencies. If you manage several brands or business units, or you are an SEO team that needs a monitoring layer tied to content updates, start here.
Pricing: OtterlyAI publishes prices on all three paid tiers.
| Plan | Price per month | Prompts | Limits |
|---|---|---|---|
| Lite | $29 | 15 | 1 workspace, 4 engines |
| Standard | $189 | 100 | Unlimited workspaces, 5,000 GEO URL audits and 2,000 API/MCP requests per month |
| Premium | $489 | 400 | 10,000 GEO URL audits and 5,000 API/MCP requests per month |
| Enterprise | Custom | From 1,000 | Custom limits, annual billing 15% cheaper |
All of that is from OtterlyAI's pricing page. The same page also shows a second, lower price set without explaining it, at $25, $160 and $422 a month for the same three plans.
OtterlyAI's help centre says ChatGPT, Google AI Overviews, Perplexity and Microsoft Copilot are included on every plan, with Gemini, Google AI Mode and Claude sold as paid add-ons. It also offers a free trial with no payment details required, though the trial length is not stated.
Strengths:
- Published prices on every paid tier, the only one of the five to do so.
- Four engines on every plan, with three more as add-ons.
- Unlimited workspaces from Standard, which suits agencies.
Trade-offs:
- Lite caps you at 15 prompts and 1 workspace, too small for a real baseline.
- Gemini, Google AI Mode and Claude cost extra.
- Two price sets on one page leave you checking which one applies at sign-up.
Key capabilities:
- Workspace support for multiple brands.
- Prompt management and reporting.
- API and MCP requests on Standard and above, plus GEO URL audits.
Good fit:
- Agencies managing multiple brands or business units.
- SEO teams that need an AI-monitoring layer tied to content updates.
- Marketing teams that want a clean path from monitoring to recommendations.
Not a fit:
- Teams that need a deeply customised enterprise data pipeline, because you may outgrow a product-led workflow and need heavier integrations.
The limitation to plan for is that visibility tracking does not tell you the fix. You still need a playbook covering content, citations, PR and technical work to turn the insight into outcomes.
4. Promptmonitor: Best For Finding Lost Prompts And Sources
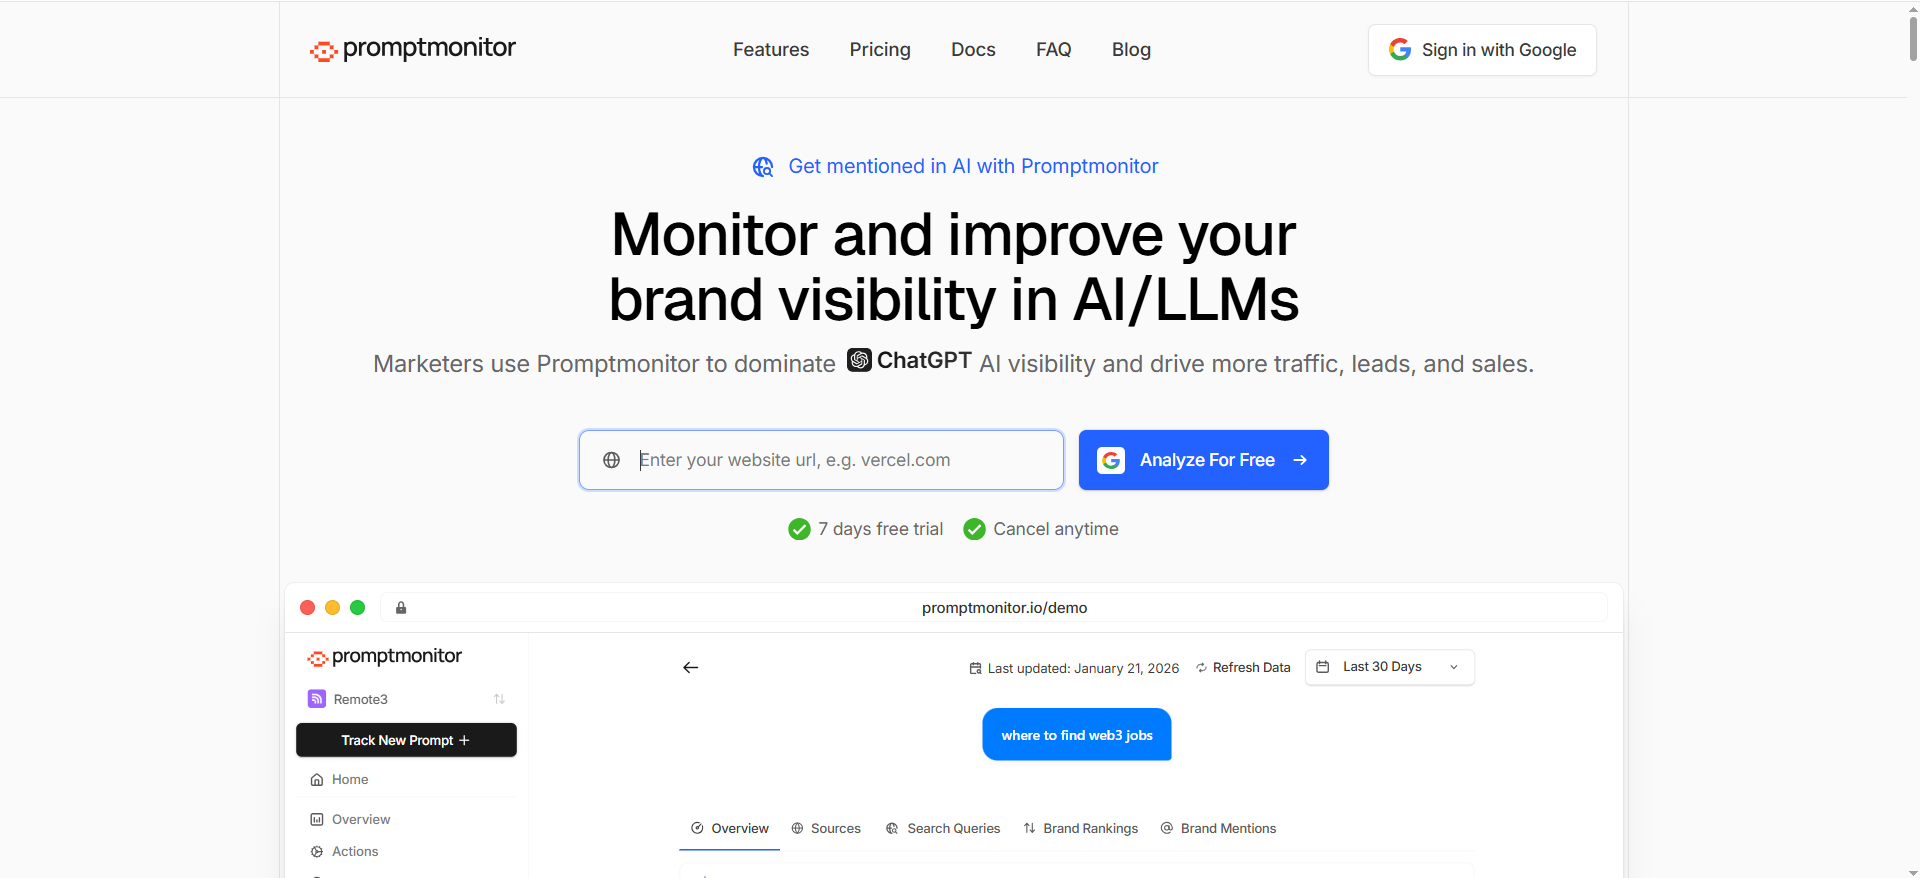
Promptmonitor tracks and improves company visibility across LLMs, with a heavy emphasis on getting mentioned and on discovering which sources AI uses. Choose it if you want an action loop more than a score, meaning a clear view of the prompts where competitors are recommended and you are absent.
Some teams want Share of Voice numbers. Others want a tight loop that asks where they are not mentioned, which sources the AI trusts, and what to change or earn to move the needle. Promptmonitor's positioning leans into that second group.
| Attribute | Detail |
|---|---|
| Pricing | Pricing on request |
| Core workflow | Mention tracking and source discovery |
| Built for | Teams turning missing prompts into action items |
Pricing: Pricing on request.
Strengths:
- Mention tracking that shows whether you are present, absent or substituted.
- Source discovery, so you see which domains show up in AI answers for your category.
- Prioritisation that turns missing prompts into action items.
Trade-offs:
- No vendor pricing page to check, so every cost question goes through the vendor.
- Governance, custom weighting and BI integration need confirming before you commit.
Key capabilities:
- Prompt tracking cadence and history.
- Competitor sets.
- Export and reporting workflow.
Good fit:
- Teams building an outreach and content strategy to earn visibility.
- Early-stage programmes where actionable insight matters more than perfect measurement nuance.
- Brands where competitor substitution is frequent and AI recommends others.
Not a fit:
- Teams that need advanced enterprise governance, custom weighting models or extensive BI integration. Confirm those capabilities early.
How to use it:
- Start with 20 to 30 high-intent prompts.
- Identify lost prompts, where competitors are mentioned and you are absent.
- Extract likely source patterns, meaning the domains and topics AI cites.
- Build a content and authority plan tied to those sources and topics.
With no published pricing, the demo is where you do your evaluation. Take these questions with you.
Questions to ask the vendor:
- How many prompts and how many runs per prompt does each plan include?
- Which engines are covered, and are any sold separately?
- Can it count a mention and a strong mention separately, so you can report two numbers?
- Can it run each prompt several times and average the result?
- What can you export, and is there an API for your BI tool?
- Does it log the full answer text, so you can audit a surprising result?
The limitation that matters most is that a tight action loop is only as good as the prompt set feeding it. If leadership expects one perfectly stable Share of Voice number, you will still need variance control, with multiple runs, averaging and weighting. Tools can support that, but your policy is what makes it credible.
5. Akii: Best For Cross-Engine Mention Tracking
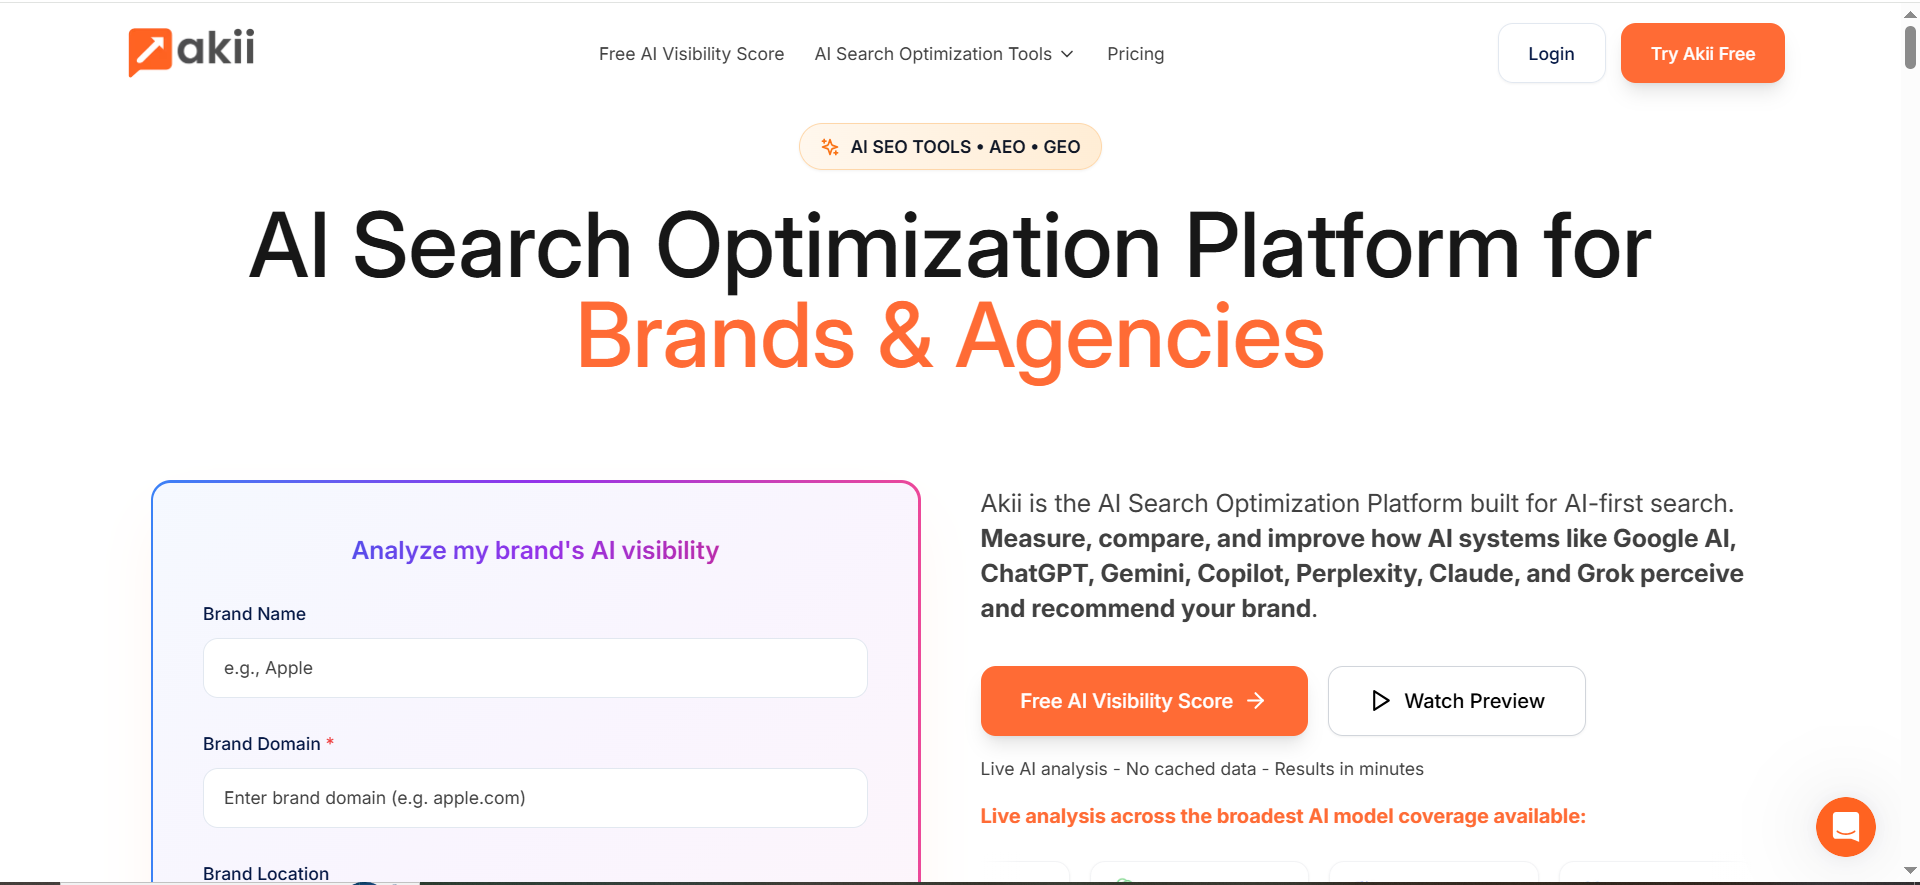
Akii markets an AI Search Tracker that monitors how often AI models mention, recommend or cite your brand across engines such as Google AI, ChatGPT and Perplexity. It fits teams that want one multi-engine view of recommendation presence.
Share of Answer lives or dies on two realities. AI answers vary, and being mentioned is not binary, because prominence and context matter. Akii's public messaging puts visibility measurement ahead of traditional SEO notions and focuses on brand presence inside AI responses.
| Attribute | Detail |
|---|---|
| Pricing | Pricing on request |
| Core workflow | Mention, recommendation and citation monitoring |
| Built for | Multi-engine or multi-market visibility |
Pricing: Pricing on request.
Strengths:
- Tracks mentions, recommendations and citations rather than mentions alone.
- Cross-engine mention tracking, so you see visibility trends across major AI surfaces.
- Competitive positioning, showing who is recommended instead of you.
Trade-offs:
- No vendor pricing page to check, so cost comes through the vendor.
- Link and citation acquisition workflows and page-level technical fixes sit outside its remit.
Key capabilities:
- Engine coverage aligned to your market.
- Prompt clustering and tagging.
- Competitor sets by category and exportable reporting.
Good fit:
- A multi-engine view for a global or multi-market brand.
- A visibility score you can use as a top-line KPI, with drill-downs.
- A programmatic way to monitor recommendation presence.
Not a fit:
- Programmes mainly about link and citation acquisition.
- Programmes that need deep SEO crawling and page-level technical fixes.
How to use it:
- Import your money topics, the prompts that decide deals.
- Create clusters for alternatives, best, integration, pricing and use case.
- Track weekly, plus daily runs for launch periods.
- Add a prominence rule so top-of-answer mentions count more than buried ones.
Questions to ask the vendor:
- Which engines are covered on each plan, and which cost extra?
- Does it separate a mention from a recommendation and a citation in the reporting?
- How many prompts and how many runs per prompt are included?
- Can you export the data and tag prompts by intent and category?
- Does it store the answer text behind each score?
The limitation that matters most is that results are only as defensible as your prompt universe and weighting. Akii can provide the tracking, but you still need a measurement policy, defined below, to avoid misleading trends.
📋 Get Listed / Advertise
We update this guide monthly. Want your tool featured? Contact: [email protected].
What Share Of Answer And Share Of Voice Mean In AI Search
Share of Answer is the percentage of tracked prompts where a brand appears in the AI answer. AI Share of Voice states that same appearance rate against a named competitor set. Your content team already knows share of voice from SEO, where it means a share of SERP visibility, and from paid, where it means impression share. In AI search the unit is not a blue link. It is an answer.
In practice, teams use these terms interchangeably. Here is a clean way to separate them.
- Share of Answer (SoA): The percentage of tracked prompts where your brand appears in the AI answer, as a mention, recommendation or citation depending on your rule set. The denominator is the number of prompts you track.
- AI Share of Voice (AI SoV): The same appearance rate, framed competitively as your rate relative to a competitor set. The denominator is every brand in that set.
- Visibility Index: A weighted version of Share of Answer that may include prompt volume, prominence or sentiment. Some platforms market it as a visibility score.
Pick one definition, write it down and never change it mid-quarter. A trend line built on a moving definition is worse than no trend line. For a deeper walk-through of the metric itself, read our guide to Share of Answer tools explained.
What Counts As An Answer: Mention, Strong Mention And Citation
Before you buy any tool or present any number, decide what counts. These are the four rules in common use.
- Mention-only rule: Your brand appears anywhere in the response.
- Recommendation rule: Your brand is recommended as an option, which is stronger than a mention.
- Citation rule: Your domain or URL is used as a source link, which is a strong authority signal.
- Top-of-answer rule: You count only if you appear in the first lines or first paragraph, as a proxy for prominence.
Tools differ on which of these they count, so confirm what a tool counts before you compare scores across vendors. A 40% in one product and a 40% in another can be two different measurements.
Report two numbers side by side. SoA (Mention) counts any appearance. SoA (Strong) counts a brand that is recommended, cited or placed at the top of the answer, or any combination of those. The two are reported together because the gap between them is the finding. A large Mention number with a small Strong number means AI knows you exist and does not rate you.
A brand can be mentioned without being cited, and the fix differs. Presence inside the answer measures the visibility layer. A citation measures the authority layer, meaning whether the engine trusts a page about you enough to link it.
- High SoA, low citations: You are mentioned, but the engine cites other sources. The work is authority and earned coverage.
- High citations, low SoA: Your content is cited in the topic area, but your brand is not positioned as the recommended choice. The work is positioning and comparison content.
Most teams should track SoA (Mention), SoA (Strong) and a citation share, meaning how often your domain is cited against competitor domains. For help closing a weak citation layer, see our Answer Engine Optimization service. To see how tools handle the mention layer, read our review of brand mention tracking tools, and for the citation layer see citation gap analysis tools.
How To Calculate A Weighted Share Of Answer
Unweighted Share of Answer is useful and easy to mislead with. A prompt asked ten times more often should count for more, and a brand recommended first is not the same as one buried at the bottom. The weighted version fixes both with two inputs.
- Set a prompt volume weight for each prompt. Where real prompt volume is unavailable, approximate it with Google keyword volume for equivalent queries, internal site search volume, or sales-call tags that show how often a question comes up.
- Score prominence on a four-point scale. Our scoring rubric gives 3 points for recommended first, 2 for recommended in the top half, 1 for mentioned but buried, and 0 for absent.
- Multiply each prompt's prominence points by its volume weight. That gives the brand's weighted points for the prompt.
- Divide the totals. Add the brand's weighted points across all prompts, and divide by the maximum weighted points, which is 3 times the volume weight, summed across all prompts.
- Weighted Share of Answer: The sum of a brand's weighted prominence points divided by the sum of the maximum weighted points, using the 3, 2, 1, 0 scale.
Here is a worked example. The numbers are invented round figures to show the arithmetic, not findings from any dataset.
| Prompt | Volume weight | Prominence points | Weighted points | Maximum weighted points |
|---|---|---|---|---|
| Prompt A | 100 | 3 | 300 | 300 |
| Prompt B | 50 | 0 | 0 | 150 |
| Prompt C | 30 | 2 | 60 | 90 |
| Prompt D | 20 | 1 | 20 | 60 |
| Total | 200 | Not applicable | 380 | 600 |
The weighted result is 380 divided by 600, which is 63.3%. The unweighted mention rate for the same four prompts is 75%, because the brand appears in three of four. The weighted number is lower because the brand is absent from a mid-volume prompt and only buried in the smallest one. That is the honest picture, and it is the one you can defend.
One published scheme scores a mention at 1, a citation at 2 and a top recommendation at 3, then divides by total points across all brands. Neither scheme is the right one. The point is to publish whichever you use, so anyone can rebuild your number.
How Many Prompts You Need For A Defensible Number
A 20-prompt set can swing wildly and mislead leadership. This ladder is the working scale we use.
| Stage | Prompts | What it is for |
|---|---|---|
| Pilot | 30 to 50 | Find signal and define the counting rules |
| Programme | 150 to 300 | Category reporting and stable trends |
| Enterprise | 500 to 2,000 | Multi-region and multi-segment coverage |
The reason for the ladder is arithmetic. A 100-answer sample at a 30% mention rate carries roughly a 9-point margin of error in either direction. You can check it yourself with the standard binomial formula.
- Formula: The margin of error is 1.96 times the square root of p(1-p)/n, where p is the mention rate and n is the number of answers.
- Simplification: This treats every answer as an independent sample.
| Answers (n) | Margin of error |
|---|---|
| 30 | About 16 points |
| 50 | About 13 points |
| 100 | About 9 points |
| 400 | About 4.5 points |
| 1,000 | About 2.8 points |
Repeat runs of the same prompt are not fully independent, so real uncertainty is somewhat higher than this table shows. Read the table as a floor.
So a pilot defines rules. It does not produce numbers for leadership. If a 30-answer pilot says you moved from 30% to 40%, you have learned nothing yet. For how often to measure once the set is big enough, see our guide to AI visibility metrics and cadence.
How To Control Variance When AI Answers Change Every Run
Answers are volatile. The same prompt can return different text on the next run, whether through model randomness, a model version change or a change in what the engine retrieves. Variance control is a short list of habits.
- Run every prompt more than once and average the results. One run is a sample of one, and averaging is the cheapest way to shrink the noise.
- Report 7-day and 28-day rolling averages. The short window catches movement, and the long window keeps you honest about it.
- Rerun any surprising result before acting on it. A sudden drop or jump is more often noise than news.
- Act only on trends that persist for several weeks. One week is an anecdote.
- Log tool and engine changes in a changelog. Surfaces change, and a metric can shift because the product changed rather than your brand.
A tool that stores the full answer text for every run makes all five steps easier. Our review of answer change detection tools covers the products that log answer differences.
How To Build A Prompt Universe And Competitor Sets
Your Share of Answer number is only as credible as your prompt universe. Start with a sample of 30 prompts split three ways, with 10 branded, 10 category and 10 problem or solution prompts.
Branded prompts inflate visibility, because an engine asked about you by name will mention you. Non-branded prompts show true category presence. Keep branded prompts in the set as a sanity check and report them separately. Do not let them lift the headline number.
Tag every prompt on three dimensions so reports turn into decisions.
- Intent tags: Best X, alternatives, X vs Y, pricing, integration, use case and reviews.
- Funnel tags: Awareness, consideration and decision.
- Category tags: Product line or solution, plus industry and region where relevant.
AI answers include direct competitors, adjacent tools, platforms and content sites such as lists and directories. So define competitor sets by category, not globally.
- Core set: Direct alternatives you meet in deals.
- Adjacent set: Tools AI recommends that sales does not see yet.
- Aspirational set: Bigger brands you want to displace over time.
If you also want to benchmark against those sets, our guide to competitor benchmarking in AI search picks up where this section stops.
The One-Page Executive Scorecard For Leadership
Execs do not want 400 prompt rows. They want three lines, and everything else is drill-down.
- Overall Share of Answer: This month against last month.
- Category share: Your three to five most important product or use-case categories.
- Competitive delta: Who is gaining or losing share against you.
Each number needs a comparison basis, or it is just a figure. Overall Share of Answer is compared with last month's figure, measured on the same prompt set and the same counting rule, so a change in the number reflects the market and not a change in the method. Category share is compared with the same category last month, and with the competitor set you defined for that category, which is why sets are built by category and not globally. Competitive delta is compared with each brand in the set over the same window, so the reader sees who moved and by how much, not just that someone did.
Put it on one page. Weighted Share of Answer trend goes top-left, competitive share goes top-right, and a category table of five rows at most, showing the biggest movers, goes along the bottom. If your tool does not give you that view, export the data to your BI tool and build it. Peec's pricing page lists a Looker Studio integration on its Advanced plan, which is one route. For the wider KPI set behind these three numbers, see our guide to AI search visibility KPIs, and for the dashboard build see Looker Studio and BI integrations.
The monthly report adds four things to the scorecard.
- Top 10 prompts to win: The lost prompts with the most volume.
- 3 content priorities: Pages to create or update.
- 3 citation targets: Sources AI already trusts in your category.
- One experiment: A single test for next month.
A scorecard that ends in actions gets read. One that ends in charts becomes a dashboard hobby.
A scorecard only helps if someone acts on it every month. The GEO + SEO Growth Programme is how we run ongoing SEO and AI-visibility work, reporting included, for B2B SaaS teams.
What To Look For In An AI Visibility Tool
A tool that meets the first four criteria below supports meaningful Share of Voice measurement. One that meets all ten can run as a programme. The first four decide the purchase, so check them before you look at anything else.
- Prompt management: Bulk upload, tagging and clustering, because you will outgrow a flat list fast.
- Competitor sets: Category-based competitor lists, not just one global list.
- Variance control: The ability to run prompts several times and average.
- Prominence support: Whether it captures where you appear, not just whether you do.
- Engine coverage: ChatGPT, Perplexity and Google AI surfaces at least. Coverage varies widely, from 3 models on Peec's Starter plan and up to 13 on Enterprise, to 4 engines on every OtterlyAI plan with three more as add-ons, to up to 9 answer engines on Profound's Enterprise tier.
- Exports and API: You will want BI integration if exec reporting matters.
- Workspaces: Crucial for agencies and multi-brand organisations.
- Alerts: A notification when visibility drops on a key prompt cluster.
- Evidence hooks: Archived answer text, so you can audit a surprising score.
- Governance: Audit trails, permissions and consistent reporting.
Engine coverage is where plans differ most, because Peec, OtterlyAI and Profound each count engines differently, and OtterlyAI sells three as add-ons. Start with the engines your buyers use, add the rest when the first set is stable, and ask whether extra engines are included or sold as add-ons.
How Much AI Visibility Tools Cost
Only one of the five publishes prices. OtterlyAI lists its Lite, Standard and Premium plans at $29, $189 and $489 a month for 15, 100 and 400 prompts on its pricing page. Peec and Profound publish plan limits and no list price for most tiers, and Promptmonitor and Akii read Pricing on request.
| Tool | What the vendor page shows | Published price |
|---|---|---|
| Peec | Limits for Starter, Pro, Advanced and Enterprise | No list price for Starter, Pro or Advanced, Enterprise by quote |
| Profound | Enterprise features and Agency Growth credits | Custom, demo required |
| OtterlyAI | Prices, prompts and limits for three paid plans | $29, $189 and $489 a month |
| Promptmonitor | Not applicable | Pricing on request |
| Akii | Not applicable | Pricing on request |
Because most prices sit behind a sales call, compare on volume. Answers per month is the number that lets you compare plans. Peec's Starter plan works out as 50 prompts times 3 models times 30 days, which is 4,500 answers a month. Do the same sum for every quote you receive.
When you ask for a quote, get these in writing.
- Prompts: How many, and how many runs per prompt.
- Models: Which engines are included and which cost extra.
- Answers per month: The total, after repeat runs.
- Seats: How many users, and whether workspaces are limited.
- Exports: CSV, API and BI connectors, and which plan unlocks them.
If you would rather have ongoing AI-visibility work and the reporting handled for you, see our ongoing GEO and SEO programme.
Do AI Visibility Tools Replace Your SEO Platform?
No. AI visibility tools do not replace SEO platforms because they measure answer presence, not search rankings. An SEO platform tells you where you rank in traditional results. An AI visibility tool tells you whether you appear when someone asks an engine for a recommendation. Teams need both, and the second does not make the first redundant.
Keep your classic SEO platform for rank tracking, keyword research and site audits. Semrush covers that work, and it also sells an AI Visibility Toolkit if you want to try the AI layer inside an account you already use before buying a dedicated tool.
The two tool types measure different things, which is why teams read both side by side. For that comparison, read our piece on share of voice in AI versus classic SERPs.
A 30-60-90 Day Rollout Plan
- Days 0-30, Pilot: Goal is to define the metric. Pick 30 to 50 high-intent prompts, define your counts-as-present rule, build competitor sets, and establish baseline variance with weekly runs.
- Days 31-60, Programme: Goal is to make the number reportable. Expand to 150 to 300 prompts, apply the tagging taxonomy, start category dashboards, and add the prominence rubric.
- Days 61-90, Optimisation: Goal is to make the number actionable. Identify lost prompt clusters and build an action backlog covering content, citations, PR and technical work. Then tie Share of Answer changes to business proxies such as demo requests, branded search lift and pipeline influence.
Do not skip the first phase to reach the dashboards sooner. Skipping it leaves the definition to be argued about later.
Common Pitfalls And Limitations Of AI Visibility Tools
Start with the mistakes you can avoid. Each one has a fix.
- Treating AI answers like stable SERPs: Answers change between runs. Use the variance rules above.
- Using too few prompts: With a tiny set, volatility looks like wins and losses when it is noise. Expand coverage and report by cluster.
- Confusing mention with recommendation: Execs hear in the answer and assume recommended. Report SoA (Mention) and SoA (Strong) together.
- Leaving competitor sets undefined: Without sets, Share of Voice becomes a vanity metric. Define them by category, aligned to deals.
- Reporting without actions: Every monthly report needs prompts to win, content priorities, citation targets and an experiment.
Then the limits no tool removes.
- Surfaces change: Metrics can shift because an engine changed, not your brand. Keep a changelog in your reporting.
- Presence is not impact: A buried mention is not a top recommendation, and many tools still simplify to mentioned or not. Use prominence scoring.
- Attribution is messy: AI engines do not send clean referral data the way SERPs do, and journeys cross channels. Pair Share of Answer with proxies such as brand search lift, direct traffic patterns, assisted conversions and sales-call mentions.
- Citation data is inconsistent: Engines cite sources in different ways and coverage varies by surface. Validate coverage engine by engine, and do not make citations your only KPI.
Entity clarity is the practical fix once tracking shows gaps. If AI cannot tell who you are and what you do, no tool will rescue your score, and that is the focus of our LLM SEO work on entity clarity.
FAQs
How Often Should Prompts Be Run, Daily Or Weekly?
Which Engines Should I Track First?
How Reliable Are The Numbers If Answers Change Every Time?
Should I Use Branded Prompts?
What Should I Do When Share Of Answer Drops Suddenly?
Are There Free AI Visibility Tools Or Trials?
How Can Agencies Scale AI Visibility Work With Dashboards?
Can One Tool Track Several AI Engines And Models Without Extra Setup?
What Is The Fastest Way To Improve Share Of Answer?
If you want a second opinion on which two tools to pilot and what belongs on your scorecard, book a thirty-minute call. One of the founders takes it, and you leave knowing what we would test first.
📑 Disclosure!
Some links in this article are affiliate links. If you sign up through them, The Rank Masters may earn a commission at no additional cost to you. This does not influence which tools we recommend or what we say about them.